Microsoft DP-700 Implementing Data Engineering Solutions Using Microsoft Fabric Exam Practice Test
Implementing Data Engineering Solutions Using Microsoft Fabric Questions and Answers
HOTSPOT
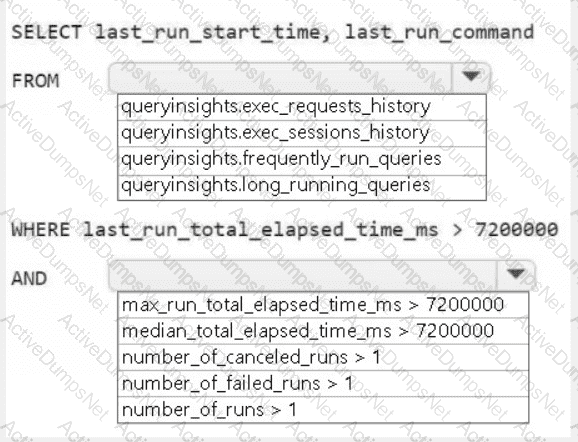
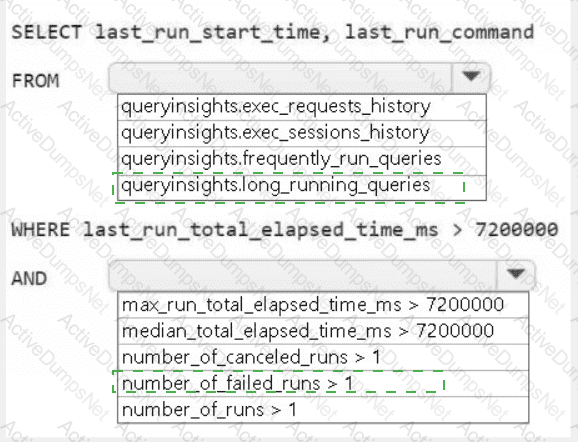
You need to troubleshoot the ad-hoc query issue.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
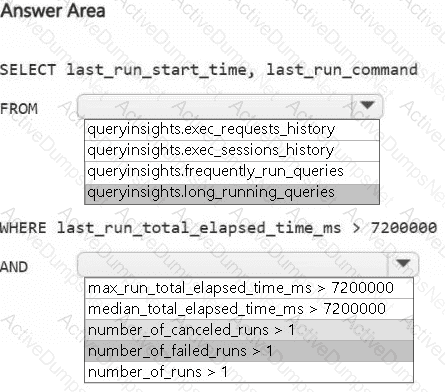 A screenshot of a computer Description automatically generated
You need to ensure that the authors can see only their respective sales data.
How should you complete the statement? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content
NOTE: Each correct selection is worth one point.
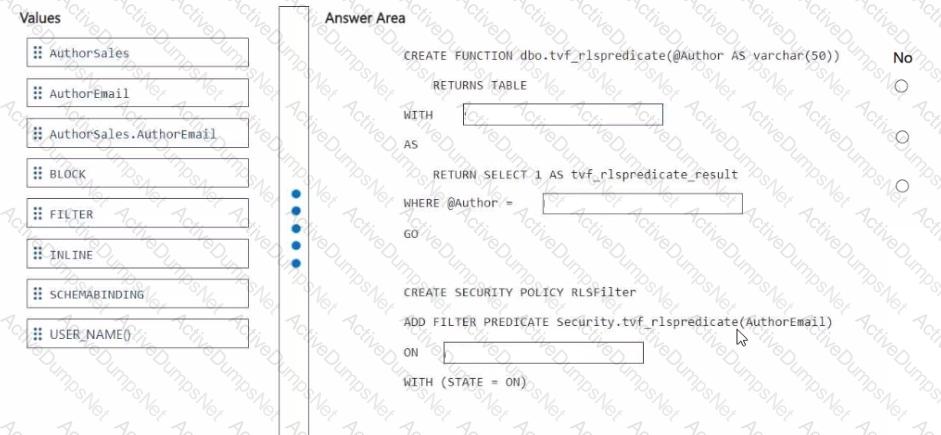
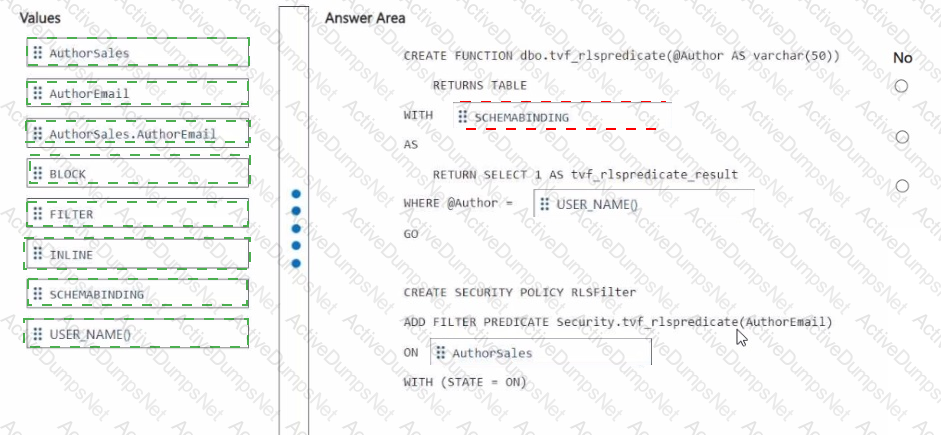
You need to create a workflow for the new book cover images.
Which two components should you include in the workflow? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
You need to resolve the sales data issue. The solution must minimize the amount of data transferred.
What should you do?
What should you do to optimize the query experience for the business users?
You need to implement the solution for the book reviews.
Which should you do?
You need to ensure that processes for the bronze and silver layers run in isolation How should you configure the Apache Spark settings?
You have a Fabric workspace that contains a warehouse named Warehouse1. Data is loaded daily into Warehouse1 by using data pipelines and stored procedures.
You discover that the daily data load takes longer than expected.
You need to monitor Warehouse1 to identify the names of users that are actively running queries.
Which view should you use?
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Lakehouse1 contains a Delta table named Table1.
You analyze Table1 and discover that Table1 contains 2,000 Parquet files of 1 MB each.
You need to minimize how long it takes to query Table1.
What should you do?
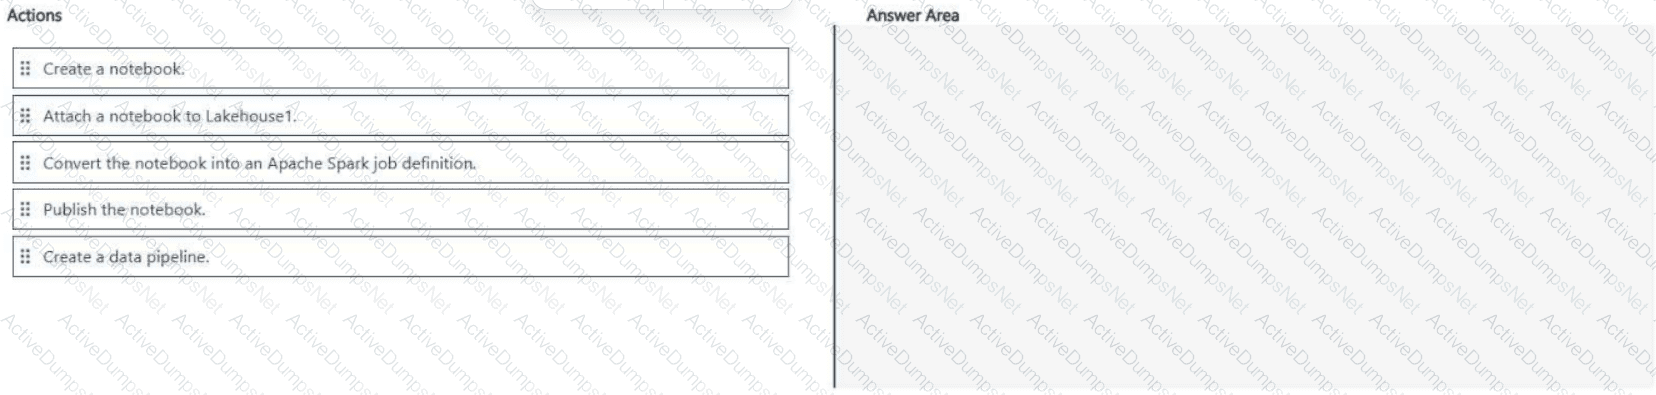
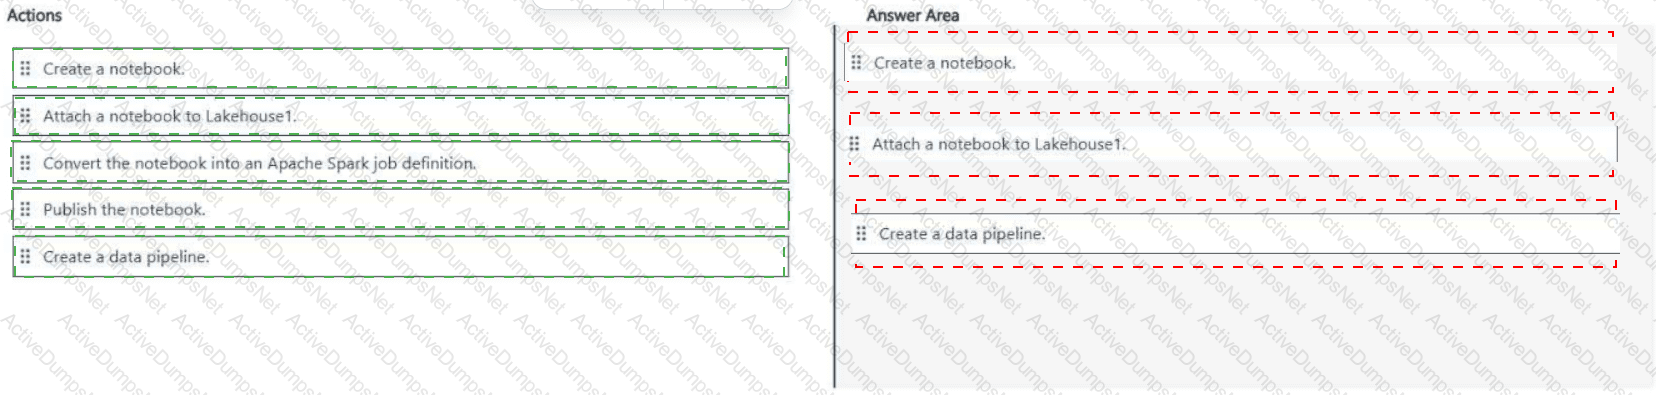
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
You need to automate a PySpark-based data transformation process. The solution must meet the following requirements:
• Ensure that users can edit and test the PySpark code interactively.
• Ensure that the code can be operationalized for automated execution.
Which three actions should you perform in sequence?
HOTSPOT
You are processing streaming data from an external data provider.
You have the following code segment.
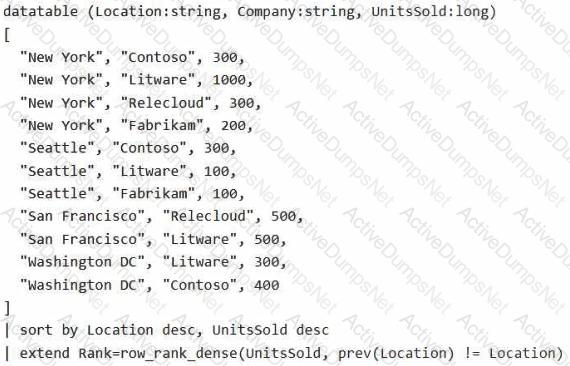
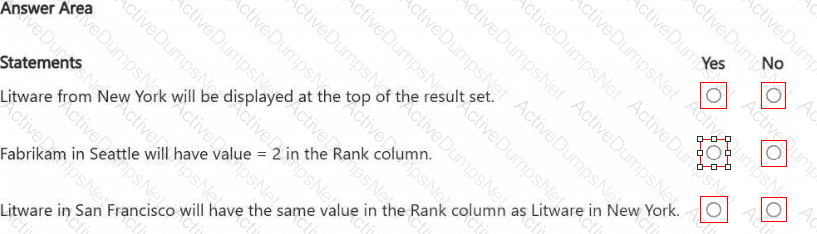
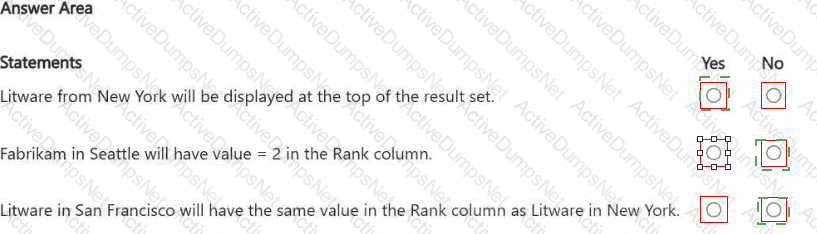
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
You have a Fabric workspace that contains 10 data pipelines named Pipeline1 through Pipeline10. The data pipelines load, transform, and publish data to a lakehouse named Lakehouse1.
Each data pipeline takes 30 minutes to run. The data pipelines must run in numerical sequence based on their names. The end-to-end process must start every eight hours.
You need to configure orchestration to ensure that all the data pipelines run in the correct order. The solution must minimize the number of schedules and administrative effort.
What should you do?
You have a Fabric workspace named Workspace1 that is connected to a GitHub repository named repo1. Workspace1 contains the items shown in the following table.
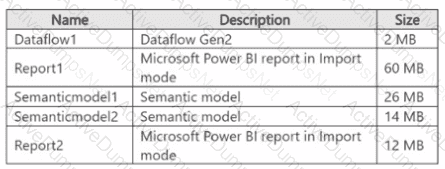
You modify Semantic model 1, Semanticmodel2, and Report2.
You need to commit the changes to repo1.
What is the minimum number of commits you should perform?
You have a Fabric workspace that contains an eventhouse and a KQL database named Database1. Database1 has the following:
A table named Table1
A table named Table2
An update policy named Policy1
Policy1 sends data from Table1 to Table2.
The following is a sample of the data in Table2.
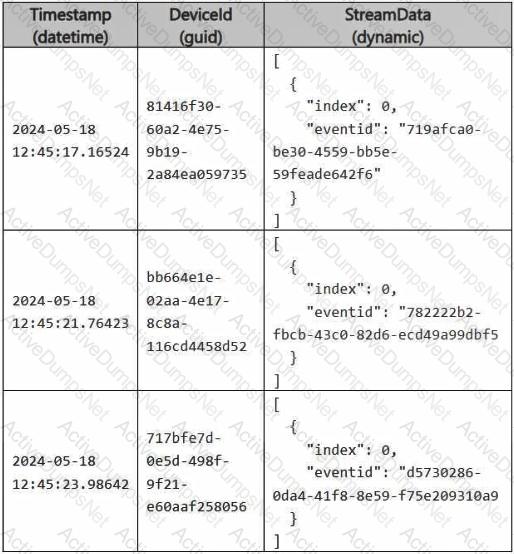
Recently, the following actions were performed on Table1:
An additional element named temperature was added to the StreamData column.
The data type of the Timestamp column was changed to date.
The data type of the DeviceId column was changed to string.
You plan to load additional records to Table2.
Which two records will load from Table1 to Table2? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
A)
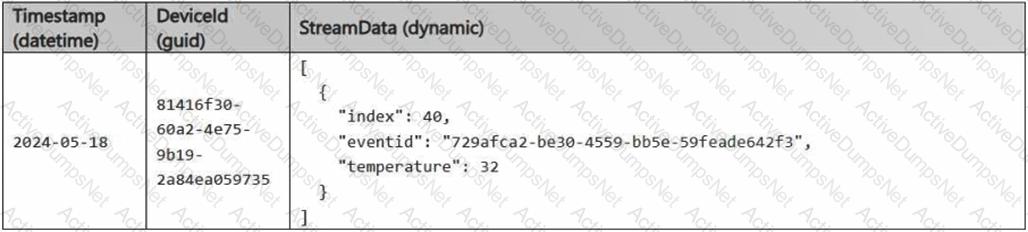
B)
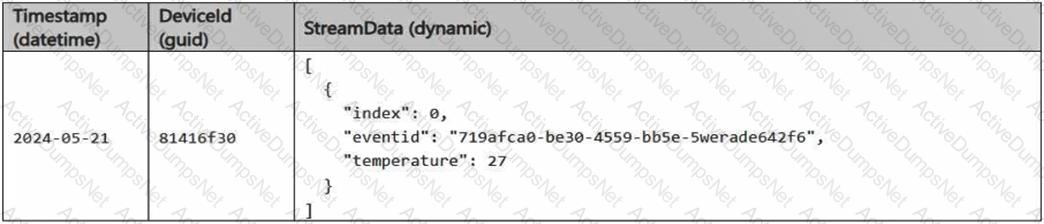
C)
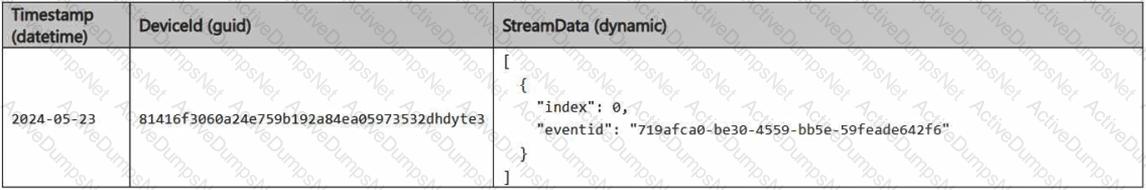
D)
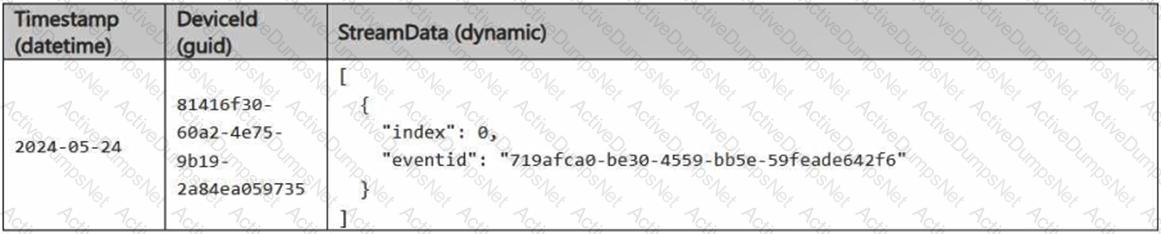
You need to recommend a solution for handling old files. The solution must meet the technical requirements. What should you include in the recommendation?
You need to create the product dimension.
How should you complete the Apache Spark SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
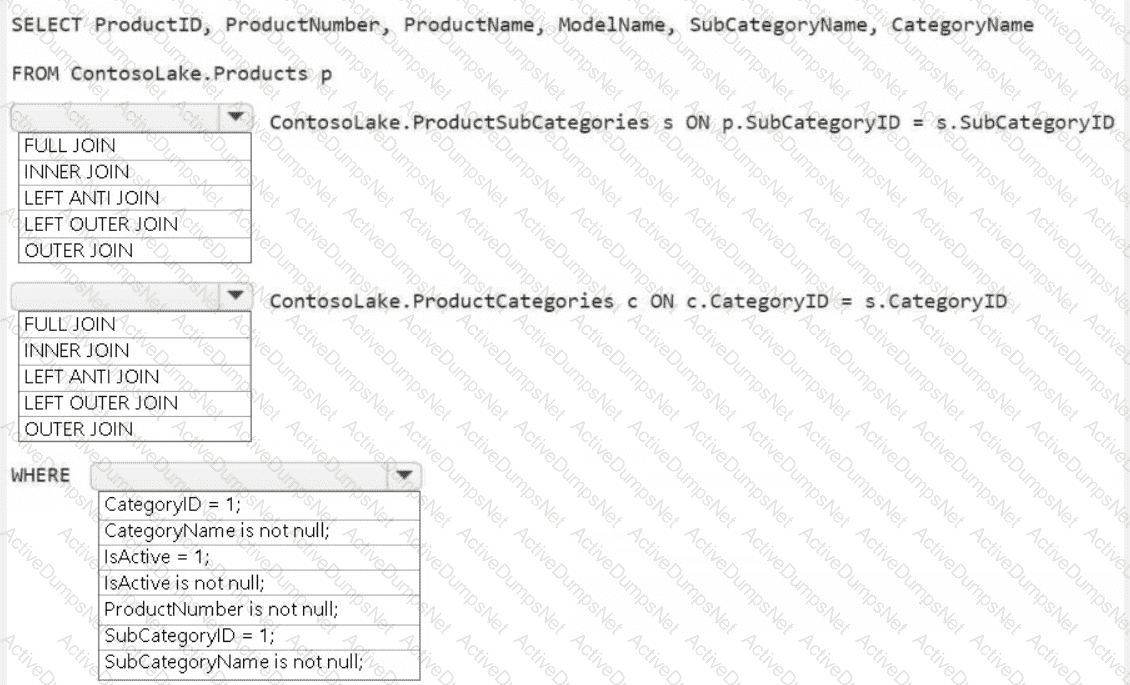
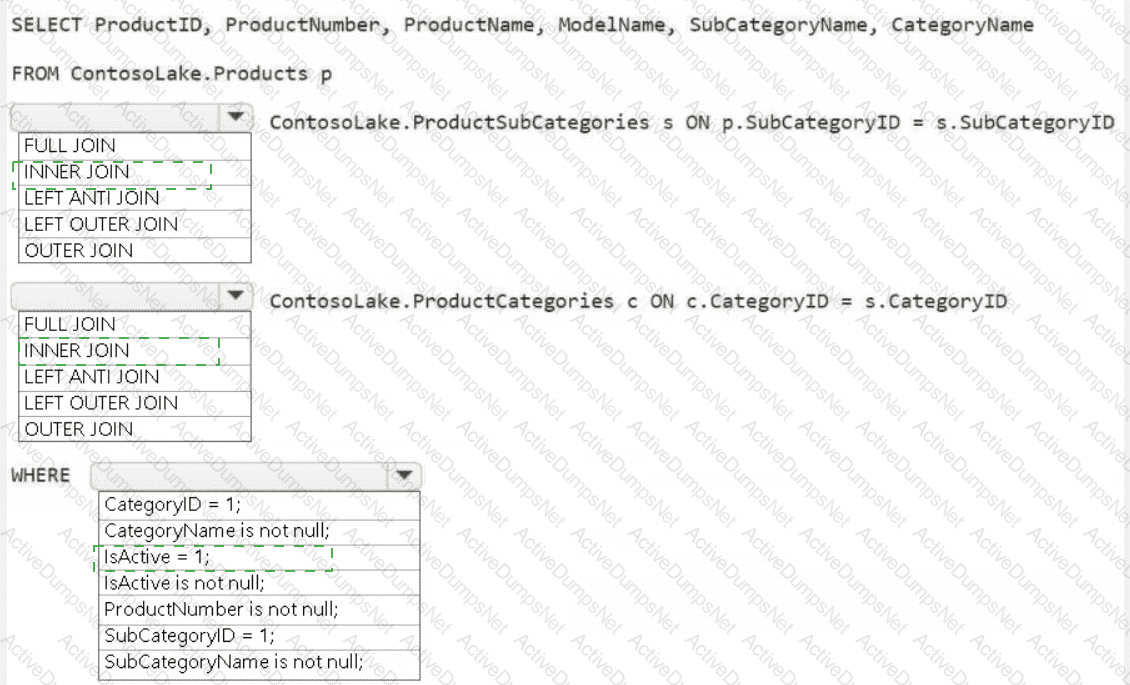
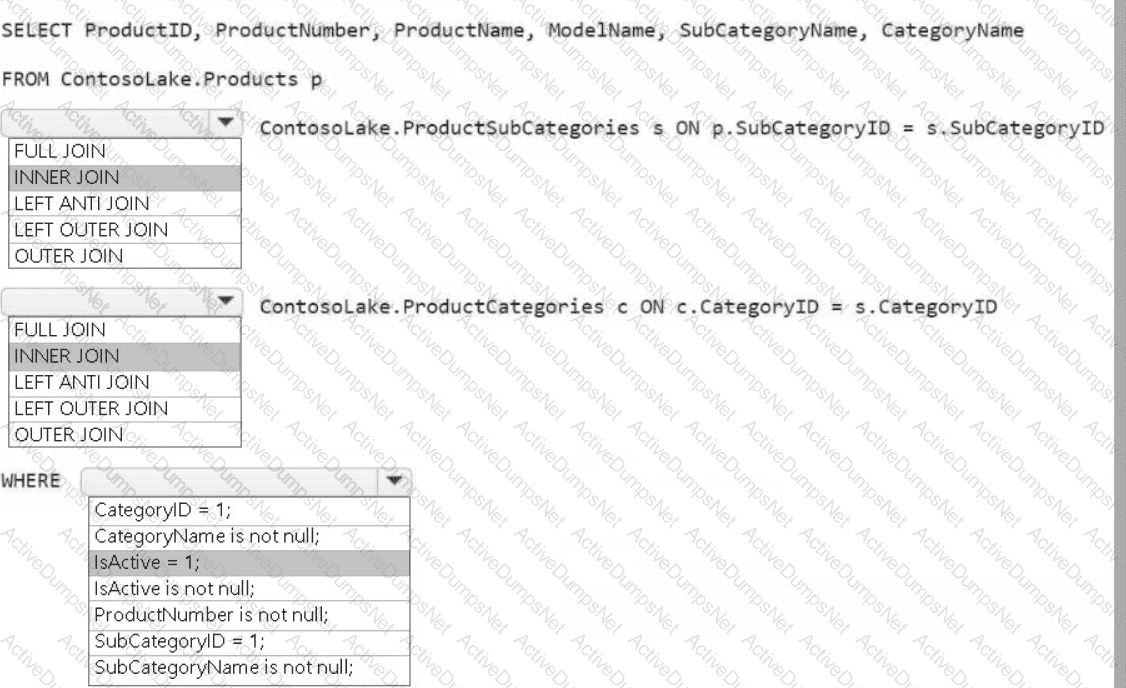 A screenshot of a computer Description automatically generated
You need to recommend a solution to resolve the MAR1 connectivity issues. The solution must minimize development effort. What should you recommend?
You need to ensure that usage of the data in the Amazon S3 bucket meets the technical requirements.
What should you do?
You need to populate the MAR1 data in the bronze layer.
Which two types of activities should you include in the pipeline? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
You need to recommend a method to populate the POS1 data to the lakehouse medallion layers.
What should you recommend for each layer? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
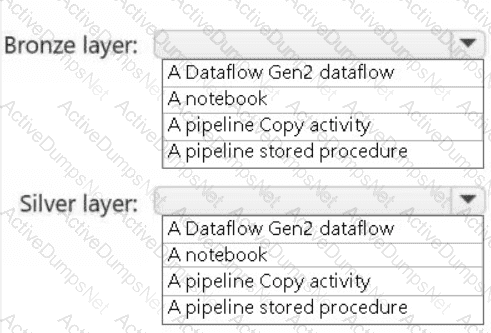

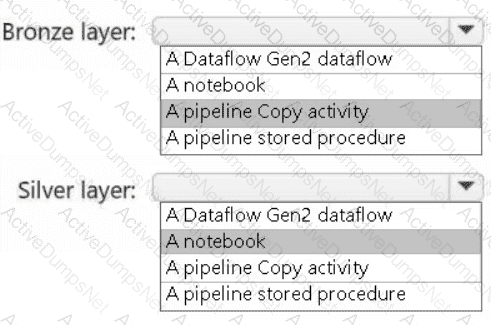 A screenshot of a computer Description automatically generated
You need to ensure that the data analysts can access the gold layer lakehouse.
What should you do?
You need to schedule the population of the medallion layers to meet the technical requirements.
What should you do?
You need to ensure that WorkspaceA can be configured for source control. Which two actions should you perform?
Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
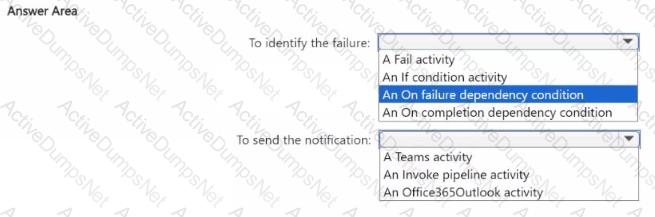
You need to ensure that the data engineer s are notified if any step in populating the lakehouses fails. The solution must meet the technical requirements and minimize development effort.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.